24 . 09 . 2026
OSINT in cybersecurity: when public information becomes useful for a cyberattack
Discover how OSINT in cybersecurity turns public data into useful context for attackers and what your company can do to reduce its exposure.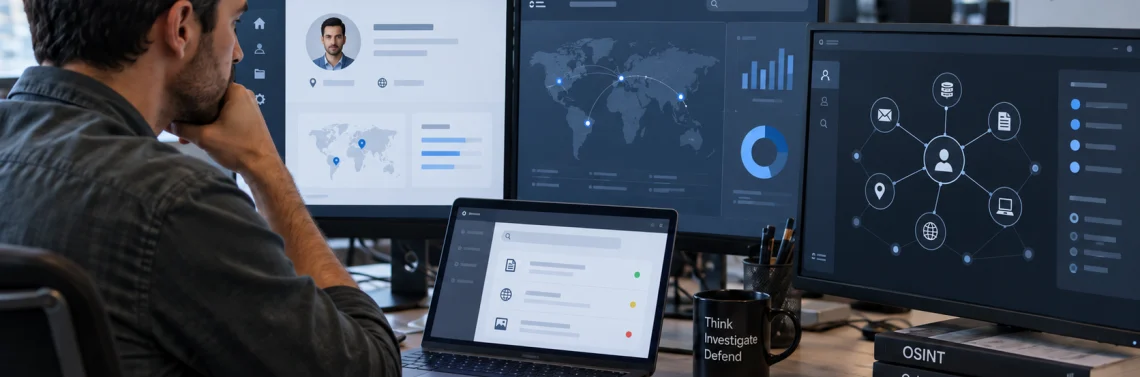
Table of contents
- What is OSINT in cybersecurity and why does it matter to a company?
- Data does not need to be confidential to have value
- The real value of OSINT lies in correlating information
- How can OSINT make a social engineering attack more credible?
- LinkedIn and an organization’s human exposure surface
- How can exposure be reduced without disappearing from the Internet?
- FAQ about OSINT in cybersecurity
- Public information does not mean information without value
OSINT in cybersecurity requires us to look at a company’s exposure from a different perspective. It is not only about what confidential information we protect, but also about what a third party can infer from information we have already made public.
This is the point raised by Pablo Alarcón, Wezen’s cybersecurity leader, regarding how everyday LinkedIn data such as job title, company, colleagues, certifications, projects, or technologies can take on a different value when connected.
Because the risk is not always in a single piece of data. It lies in the context that can be built by combining multiple pieces of information.
In this article, we examine how this works, why it matters for cybersecurity, and what an organization can do to better manage its exposure.
What is OSINT in cybersecurity and why does it matter to a company?
OSINT, or Open Source Intelligence, is the process of collecting, evaluating, and analyzing publicly available information to turn it into useful intelligence. In cybersecurity, it can be used by both defensive teams and malicious actors.
For this reason, OSINT should not be understood as an inherently malicious activity. It can be part of security investigations, threat analysis, or exposure assessments. The problem arises when those same sources are used during reconnaissance before an attack.
Professional profiles, corporate websites, job postings, social media posts, repositories, news, or technical documentation can provide different pieces of information.
There is also a fundamental distinction: an inference obtained through OSINT is not automatically a fact.
If someone states publicly that they manage Microsoft 365, for example, that can provide context about their role or certain technologies related to their work. By itself, it does not demonstrate how the company’s infrastructure is configured.
An inference is a hypothesis. Its value increases when it can be validated and correlated with other sources, Pablo emphasizes in his analysis.
Data does not need to be confidential to have value
When an organization analyzes its exposure, it often asks: “Are we publishing confidential information?”
That question is necessary, but it may not go far enough.
It is also worth asking:
“What could someone infer by combining what we have already published?”
Name, company, job title, tenure, colleagues, certifications, technical expertise, or participation in specific projects are common pieces of information on the Internet. None of them needs to be sensitive on its own.
However, when correlated, they can help reveal people, responsibilities, and processes.
From public data to a useful hypothesis
Consider someone who posts: “Treasury Analyst — Company XYZ.”
That information does not reveal a wire transfer or banking information. But it may suggest that the person is involved with payments, vendors, or certain financial processes.
Now consider: “Microsoft 365 Administrator — Company XYZ.”
This does not reveal a configuration or credential either. But it can provide context about technologies and identify someone with potentially relevant technical responsibilities.
The logic can be summarized as follows:
DATA → CONTEXT → RELATIONSHIP → INFERENCE
For this reason, the value of information should not be assessed solely by looking at each piece of data independently.
The real value of OSINT lies in correlating information
Someone conducting reconnaissance does not need to look at LinkedIn in isolation.
They can correlate information from different sources:
- professional profiles and social media;
- websites and corporate posts;
- job postings;
- press releases and events;
- repositories and public documentation;
- vendors, partners, and conferences.
A company post may reveal who leads a project. A professional profile can identify that person’s role. A conference may provide information about certain technologies. A job posting can offer additional clues about the environment.
No single source needs to reveal the full picture. This is one of the central ideas in Pablo’s analysis: OSINT is not simply about finding data, but about understanding the relationships that can be established between different pieces of information.
Job postings can also reveal technological context
Recruiting is a good example.
A company may be looking for a professional with experience in AWS, Kubernetes, Terraform, specific firewall solutions, EDR, or identity platforms. Including these technologies makes sense when trying to attract qualified candidates.
But from another perspective, that same job posting can generate hypotheses about part of the organization’s technology ecosystem.
This does not mean that every solution mentioned is actually implemented, much less that a company’s architecture can be determined from a job posting.
It does mean that this information can help narrow the search space and guide new hypotheses.
How can OSINT make a social engineering attack more credible?
An attacker does not always need to obtain confidential information first.
In some cases, they need something different: enough context to appear credible.
Knowing someone’s company, responsibilities, managers, a vendor, a recent project, or certain technologies can help build communications that better fit that person’s environment.
The process can be thought of as follows:
COLLECT → CORRELATE → INFER → CONTEXTUALIZE → APPROACH
Recent research shows that this type of reconnaissance is not merely a theoretical possibility.
In September 2026, Microsoft Security Research documented active intrusions in which attackers appeared to invest significantly in researching their targets beforehand. They did so by gathering information about employees and organizational structures from public sources, including social media and professional networking platforms.
In another campaign documented in April 2026, Microsoft observed the use of automation and artificial intelligence to personalize lures based on the victim’s role, using topics related, for example, to RFPs, invoices, and manufacturing workflows.
The knowledge obtained does not exploit only a technical vulnerability. It can be used to exploit something different: trust.
AI makes it possible to scale personalization
In the past, researching each victim and tailoring a communication required time.
Now, AI can reduce some of that barrier.
A study presented at USENIX Security 2026 analyzed personalized spear phishing using language models with 7,700 participants.
Researchers used web searches to gather information about targets and automatically generate tailored messages. LLM-based spear phishing nearly tripled the click-through rate compared with generic strategies, at an approximate cost of USD 0.03 per personalized email within the experiment.
The relevant change is not only that AI can write a more convincing message. It is that part of the research and personalization process can be automated and applied at a greater scale.
This expands on a risk we previously analyzed in AI-assisted phishing: technology did not invent social engineering, but it can increase the speed, volume, and level of personalization with which it is carried out.
LinkedIn and an organization’s human exposure surface
None of this means that LinkedIn is an insecure platform or that the solution is to ask employees to disappear from the Internet.
LinkedIn provides professional, commercial, and networking value. Pablo’s own analysis begins by recognizing these benefits and instead proposes making conscious decisions about how much information is exposed.
From this perspective, we can expand the traditional concept of the attack surface and also consider a human exposure surface.
When we talk about exposure, we usually think of servers, IP addresses, applications, VPNs, cloud services, or domains.
But information about people can also provide context:
- who holds certain roles;
- who may have critical responsibilities;
- what technologies they are familiar with;
- who participates in certain processes;
- what type of communication might seem normal to that person.
In other words, this information does not need to provide direct access to a system to be valuable.
It can help build a story coherent enough to try to persuade someone who already has that access.
How can exposure be reduced without disappearing from the Internet?
The answer is not to hide all information.
It is to manage exposure consciously.
Look at the organization from the outside
A good starting point is to ask what someone without internal access could learn by looking at what the organization already publishes.
Professional profiles, the corporate website, job postings, case studies, events, and documentation can all be analyzed from this perspective.
The goal is not only to identify confidential information. It is also important to understand what relationships or processes could be inferred by combining it.
Evaluate what information really needs to be public
Not all data provides the same value, and not all roles have the same level of exposure.
Before publishing information about structures, responsibilities, technologies, or projects, it is worth assessing whether that level of detail is necessary to achieve the communication’s objective.
The goal is not to stop communicating. It is to incorporate risk into the decision.
Pay special attention to certain roles
Finance, Treasury, Human Resources, Procurement, IT, Cybersecurity, Help Desk, and executive positions deserve particular attention.
These roles may be involved in payments, contracts, access, sensitive information, or critical decisions. In his analysis, Pablo identifies them as particularly relevant from this perspective.
Integrate human exposure into the security strategy
Managing public information is only one part of the response.
Identity protection, phishing-resistant MFA where appropriate, access controls, monitoring, verification procedures, and training should work together.
It is also important to verify that these measures work in practice. As we discussed in our analysis of cybersecurity controls, having controls does not automatically reduce risk: they must be properly implemented, prioritized, and evaluated according to the scenario they are intended to protect.
The human dimension also requires this approach. Cybersecurity training tailored to specific roles and risks can help people recognize social engineering attempts that seem credible precisely because they use information related to their everyday work.
Because technical and human risk do not operate as two separate worlds.
FAQ about OSINT in cybersecurity
What does OSINT mean in cybersecurity?
It is the collection and analysis of publicly available information to obtain useful intelligence about people, organizations, technologies, or threats.
Can public information pose a risk to a company?
Yes. Although an individual piece of information may not be sensitive, combining it with other sources can make it possible to infer relationships, responsibilities, processes, or technologies.
What is the relationship between OSINT and social engineering?
OSINT can provide context about a person or organization and be used to build social engineering communications that are more consistent with their environment.
Can LinkedIn be a source of information for OSINT?
Yes. Professional profiles can provide information about roles, relationships, and expertise. The risk depends on what can be inferred when that information is correlated with other sources.
How can a company reduce its human exposure surface?
By reviewing what information it makes public, what can be inferred by combining it, and how it protects higher-risk roles, identities, and processes.
Public information does not mean information without value
Organizations need to continue strengthening identities, endpoints, applications, infrastructure, and monitoring.
But security also requires understanding how an attack could be prepared before anyone attempts to compromise a system.
If a technical barrier is difficult to overcome, an attacker may try to persuade someone who already has access. And to do that, they need context.
Some of that context can be found without bypassing a firewall or compromising an account.
That is why, in addition to asking:
“Are we publishing confidential information?”
it is worth adding a second question:
“What could a third party infer by combining everything our organization has already made public?”
This shift in perspective makes it possible to broaden risk management and view the organization as someone from the outside might see it.
If this analysis raises questions about how prepared your organization is for attacks that combine public information, identity, and the human factor, at Wezen we can help you assess your security posture and prioritize improvements based on the actual risk to your operations. Write to us.
Image: Image generated with ChatGPT Images 2.5, OpenAI, 2026
Sources consulted
- Czybik, S., Kouam, A. J., Heubl, P., Nold, J. M., & Rieck, K. (2026). A Large-Scale Study of Personalized Phishing using Large Language Models. In 35th USENIX Security Symposium (USENIX Security 26) (pp. 1687–1706). USENIX Association. URL
- Microsoft Defender Security Research Team. (2026, April 6). Inside an AI-enabled device code phishing campaign. Microsoft Security Blog. URL
- Microsoft Security Research. (2026, September 9). Passkey-themed social engineering leads to identity and cloud compromise. Microsoft Security Blog. URL
- Sargeant, S. (2026, July 13). What is open source intelligence (OSINT)? Trend Micro. URL
Related articles
How to address the specialized cybersecurity talent gap in the age of AI
Lack of specialized cybersecurity talent. Discover how to address this with effective strategies, training, and managed services.
Unified Access: The key to secure unified access
Unified Access enables a consistent and secure experience across wired and wireless networks. Discover how it improves connectivity, security and IT operations.